From Autocomplete to Assistant: Instruction-Tuned and Chat Models
Why GPT-2 rambles and a chat model answers: base versus instruct, the same question put to both, the chat template that turns roles into tokens, multi-turn memory written as code, and streaming replies — running Qwen2.5-0.5B-Instruct on a free GPU or a plain CPU.
GPT-2 taught you how a model writes — but it only ever continues text. Ask it a question and it hands you a column of newlines. The models you actually talk to, the ones that answer instead of ramble, have one extra ingredient: they were instruction-tuned, taught on top of all that next-token prediction to be helpful. This chapter is the bridge from autocomplete to assistant — the last idea you need before you build the finale — and it runs the same question through a base model and its instruct twin so you can see what the tuning buys and, just as important, what the chat template buys.
We’ll use Qwen2.5-0.5B-Instruct — tiny, ungated, Apache-2.0, and comfortable on a free Colab GPU or, slowly, a laptop CPU.
▶ Open the companion notebook in Colab
Run against: PyTorch 2.2.2 and transformers 4.57.6 on CPU (macOS), device="cpu" in place of the device_map="auto" shown (see chapter 9’s Mac note); greedy decoding throughout so the outputs are reproducible.
Base vs instruct: same model, extra schooling
Every chat model starts as a base model — a GPT-style decoder trained to predict the next token on a mountain of text. That gives it fluency and knowledge, but no manners: it doesn’t know it’s supposed to answer you. Instruction tuning is a second round of training on examples of requests and good responses, which teaches the model to treat your input as something to act on rather than continue.
You can spot the difference in the model’s name: a ...-Instruct or ...-Chat suffix means it went through that second round. Qwen2.5-0.5B is the base; Qwen2.5-0.5B-Instruct is the one that answers. Here is the same question, put to both as a plain string, the way chapter 22 prompted GPT-2:
from transformers import AutoTokenizer, AutoModelForCausalLM

q = "What is the capital of France? Answer in one sentence."

for name in ["Qwen/Qwen2.5-0.5B", "Qwen/Qwen2.5-0.5B-Instruct"]:
    tok = AutoTokenizer.from_pretrained(name)
    model = AutoModelForCausalLM.from_pretrained(name)
    ids = tok(q, return_tensors="pt")
    out = model.generate(**ids, max_new_tokens=40, do_sample=False)
    print(name, "->", repr(tok.decode(out[0][ids["input_ids"].shape[1]:], skip_special_tokens=True)))
Qwen/Qwen2.5-0.5B -> ' The capital of France is Paris.'
Qwen/Qwen2.5-0.5B-Instruct -> ' The capital of France is Paris. It is a city located on the Seine River, which flows through the heart of the country. Paris is known for its iconic 'That is not the result the folklore predicts, and it is more instructive. The base model, fed a raw question, continued it with a correct one-sentence answer — a crisp factual question is common enough on the web that “the answer” is the likeliest continuation. The instruct model, fed the same raw string, ignored “in one sentence” and kept going. Instruction tuning did not make the model answer; the model could already do that. What is missing is the second shift.
Talking to it with roles
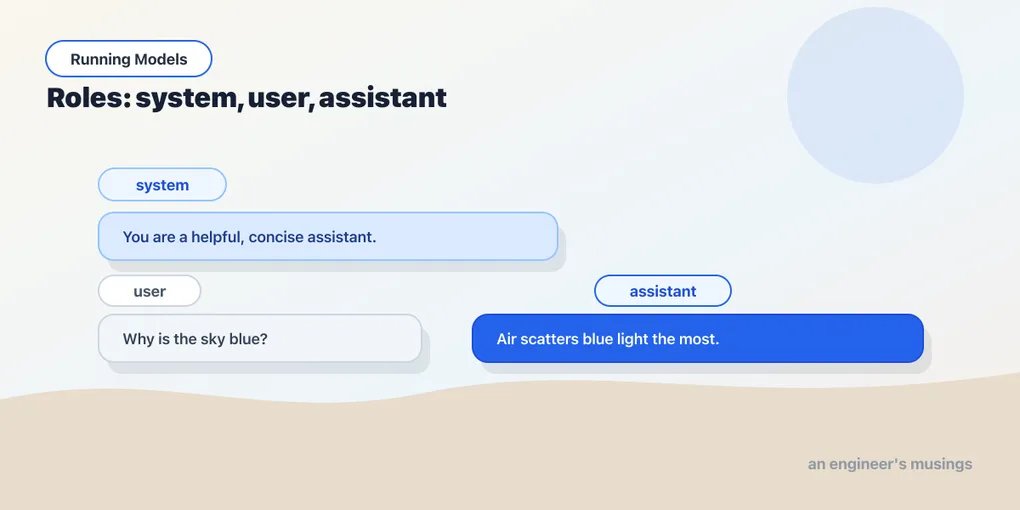
Chat models don’t take a plain string, they take a conversation — a list of messages, each tagged with a role:
system— standing instructions for how to behave (“You are a terse, friendly assistant.”).user— what the person said.assistant— what the model said (the model fills these in; you include past ones for multi-turn memory).
Hand the instruct model the question as a message, and the constraint is honoured:
messages = [{"role": "user", "content": q}]
ids = tok.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt")
out = model.generate(ids, max_new_tokens=40, do_sample=False)
print(tok.decode(out[0][ids.shape[1]:], skip_special_tokens=True))
# The capital of France is Paris.
One sentence, as asked. The difference between the ramble and the answer was not the weights — same model both times — but the format the question arrived in. Instruction tuning taught the model to answer requests that look like the requests it was tuned on, and those requests came wrapped in roles.
The modern pipeline understands this format directly — hand it messages instead of a string:
from transformers import pipeline

chat = pipeline("text-generation", model="Qwen/Qwen2.5-0.5B-Instruct", device_map="auto")

messages = [
    {"role": "system", "content": "You are a helpful assistant who answers in one sentence."},
    {"role": "user", "content": "Why is the sky blue?"},
]

out = chat(messages, max_new_tokens=80)
print(out[0]["generated_text"][-1]["content"])
# The sky appears blue because of the scattering of sunlight by tiny water droplets in the Earth's atmosphere, ...
That last line looks fiddly, so read it slowly: the pipeline returns the full conversation — a list of three messages now, system, user, and the model’s reply appended as a new assistant message — so [-1]["content"] is just “the text of the last message.” One sentence, as the system prompt asked. Also wrong: the sky is blue because air scatters blue light, not water droplets, and a 494-million-parameter model will get that kind of thing wrong. Fluent, obedient, and mistaken is a normal output; chapter 22’s last gotcha has not stopped applying.
What the chat template does
Under the hood the model still only sees one long string of tokens — so how do roles survive? Each chat model ships a chat template that formats your messages into the exact special tokens it was trained on. The pipeline applies it for you, but you can see it:
print(tok.apply_chat_template(messages, tokenize=False, add_generation_prompt=True))<|im_start|>system
You are a helpful assistant who answers in one sentence.<|im_end|>
<|im_start|>user
Why is the sky blue?<|im_end|>
<|im_start|>assistantThose <|im_start|> and <|im_end|> markers are tokens the model saw millions of times during tuning, and add_generation_prompt=True ends the string with an open assistant turn, which is the model’s cue to speak. This is what the raw-string experiment lacked: without the markers, the instruct model was never told a request had ended and its turn had begun. The lesson: use the model’s own template (which apply_chat_template and the pipeline do automatically) — hand-formatting a prompt and getting those markers wrong is a top reason a chat model gives mediocre answers. Let the tokenizer do it.
Memory is just the history you resend
A chat model is stateless. It remembers nothing between calls; what looks like memory is the conversation so far, sent again every turn. The pipeline makes this concrete, because what it returns is exactly what you send next:
history = [
    {"role": "system", "content": "You are a terse assistant."},
    {"role": "user", "content": "My name is Sam. Remember it."},
]
history = chat(history, max_new_tokens=30, do_sample=False)[0]["generated_text"]   # now 3 messages

history.append({"role": "user", "content": "What is my name?"})
reply = chat(history, max_new_tokens=20, do_sample=False)[0]["generated_text"][-1]["content"]
print(reply)   # Your name is Sam.
Drop the history and ask the second question cold, and the same model says I'm sorry, but I don't have any personal information or names to share. Every chat window you have ever typed into is doing this append-and-resend behind the scenes, which is also why long conversations get slow: the prompt grows by one exchange per turn.
Watching the reply arrive
Generation is a loop, and nothing says you have to wait for it to finish before showing the tokens. A streamer prints each token as the loop produces it — the typing effect every chat UI has:
from transformers import TextStreamer

streamer = TextStreamer(tok, skip_prompt=True)
chat([{"role": "user", "content": "Count to five."}], max_new_tokens=20, do_sample=False, streamer=streamer)
# Sure! Here's how I count to five:
# 1. One
# 2. Two
# 3.
The text appears a token at a time (and stops at twenty, mid-list, because that was the budget). For a notebook TextStreamer is enough; a web UI uses the same idea with TextIteratorStreamer, which hands you the tokens as a Python iterator to forward to the browser.
Sampling still applies
Everything from chapter 23 carries straight over — a chat model generates with the same knobs:
chat(messages, max_new_tokens=120, do_sample=True, temperature=0.7, top_p=0.9)Lower temperature for factual answers, higher for brainstorming. The decoding skills you learned on GPT-2 are exactly the ones you’d set on any chat model or hosted API.
Gotchas
- Use the
-Instruct/-Chatvariant for tasks. The base model is for continuation; the instruction-tuned one is for answering — and, as the first experiment showed, only when you talk to it in its format. - Don’t hand-format prompts. Pass
messagesand letapply_chat_template(or the pipeline) insert the special tokens. A raw string to an instruct model gets you the ramble above. - Include history for multi-turn memory. The model only “remembers” what you resend. The pipeline’s return value is the conversation to resend; append the next user message to it.
- Small instruct models are limited. A 0.5B model is great for learning and light tasks, but it will get facts wrong (the sky, above) and lose the thread on hard ones. It’s the right size to understand chat models, not to replace a frontier one.
- A system prompt steers a lot. Changing the
systemmessage (“answer in one sentence,” “reply as a pirate”) visibly changes behaviour — it’s the cheapest, most underused knob. device_map="auto"picks your accelerator. On a Colab GPU that is what you want. On a Mac with an older PyTorch it may pick MPS and fail to load abfloat16checkpoint;device="cpu"is the fix, as chapter 9 says.
What’s next
You now understand the whole chat stack: a base model for fluency, instruction tuning for helpfulness, roles and a chat template to carry a conversation, a history you resend for memory, a streamer for the typing effect, and sampling to shape the replies. Every concept the book needs is on the table.
So let’s build the thing everyone pictures when they hear “AI app” — wrap this chat model in a real conversational UI you can share.
Comments